
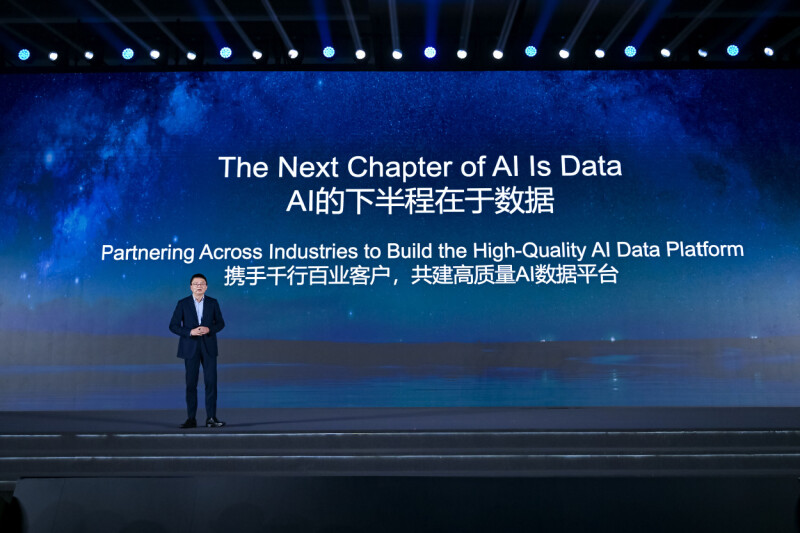
AI inference is running into a memory bottleneck. Huawei wants to tackle it with OceanStor M900
AI Summary
As organizations move from straightforward AI interactions towards longer conversations, complex reasoning and autonomous agents, the demands on their infrastructure are changing. Processing increasingly large amounts of context places significant pressure on memory capacity, while keeping accelerators supplied with data becomes just as important as raw computing power. One particular challenge is the key-value (KV) cache, which stores information generated during inference so models can reuse p
Discussion
Sign in to join the discussion.
Loading comments…