
No GPU, No Problem: Flagship LLMs on a GPU-less Teenaged Server
AI Summary
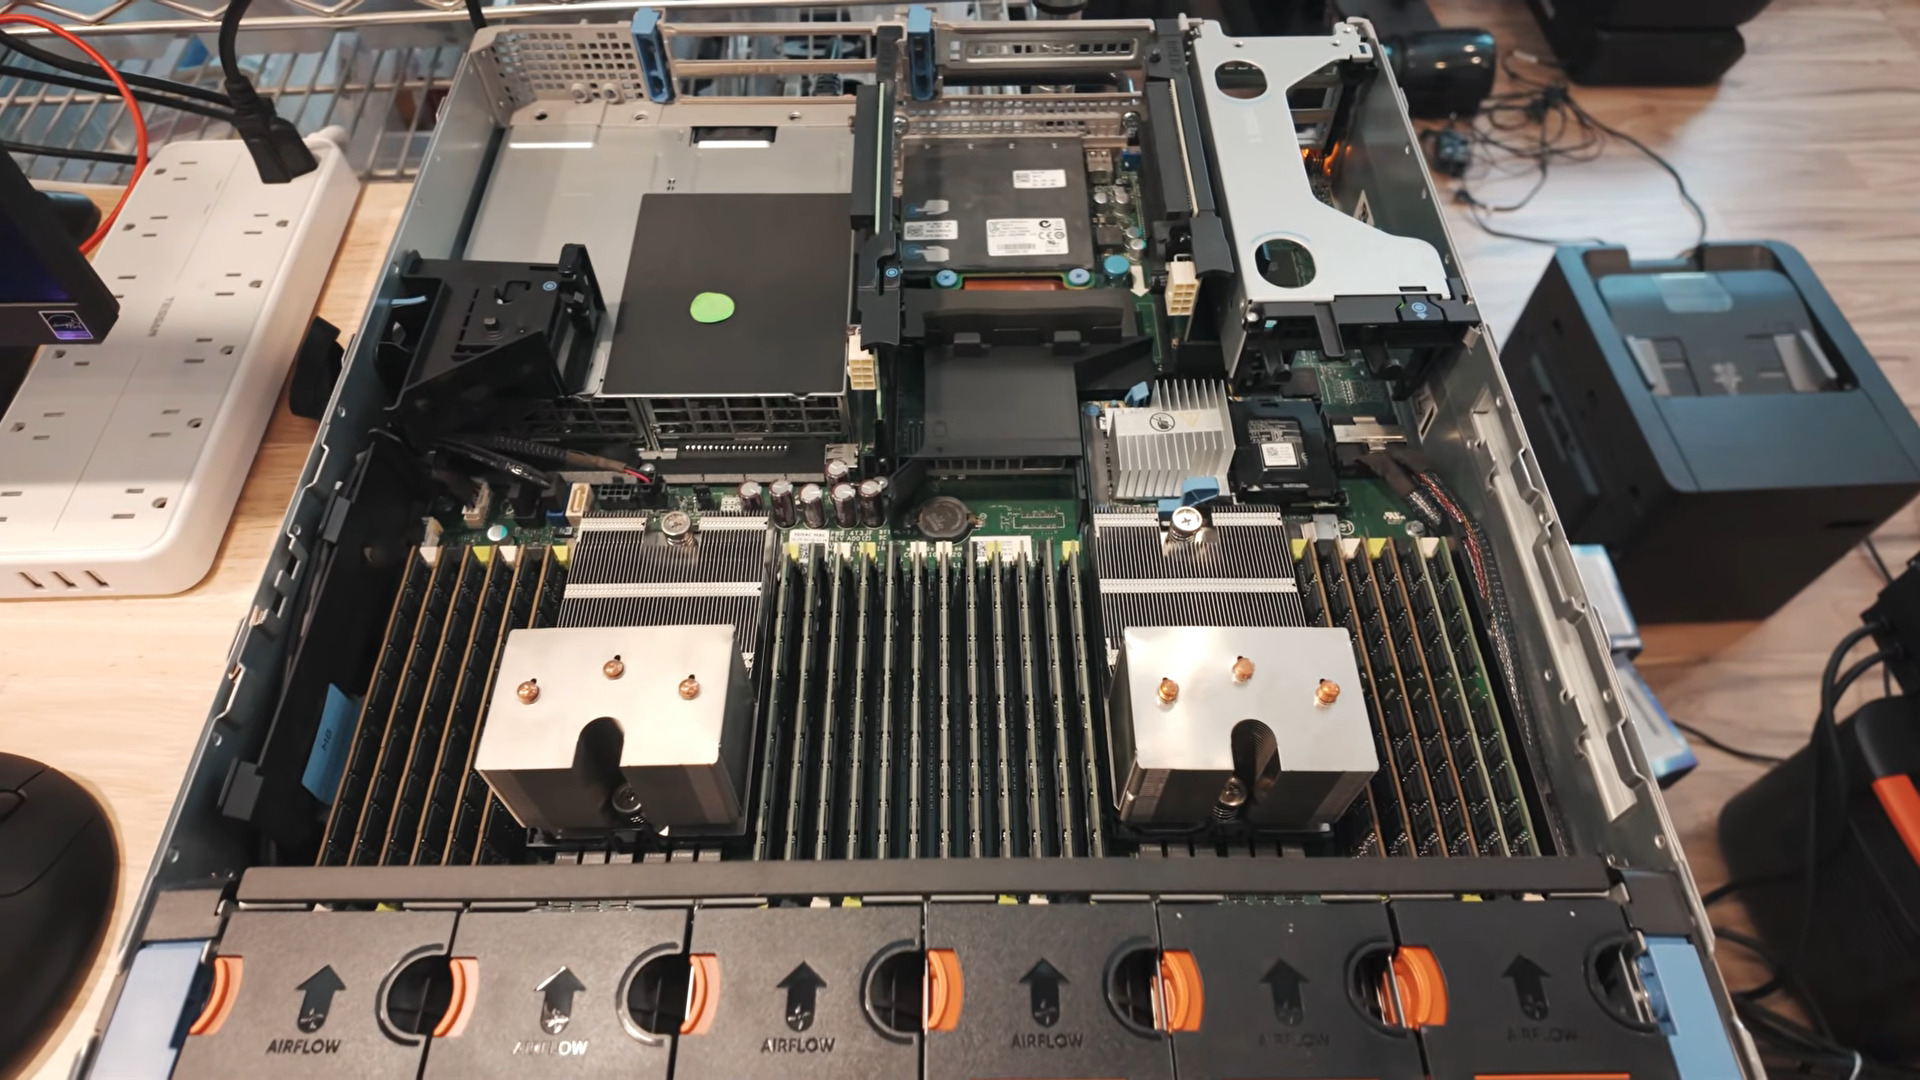
There are lots of reasons to run LLMs locally, from privacy concerns to just wanting to futz about with the technology, but if you want to run the big models, the standard logic is that you need big money for lots and lots of VRAM. [MattMo] is calling that into question with his recent video — embedded below, naturally — in which he gets GLM 5.3 Flash, Qwen 3.8 Flash and Qwen 3.8 27B all running on a 14-year-old server without a single GPU. The secret, if you can call it that, is that they aren’
Discussion
Sign in to join the discussion.
Loading comments…